benchfmt.rs: Bringing Go's Benchmarking and benchstat Workflow to Rust
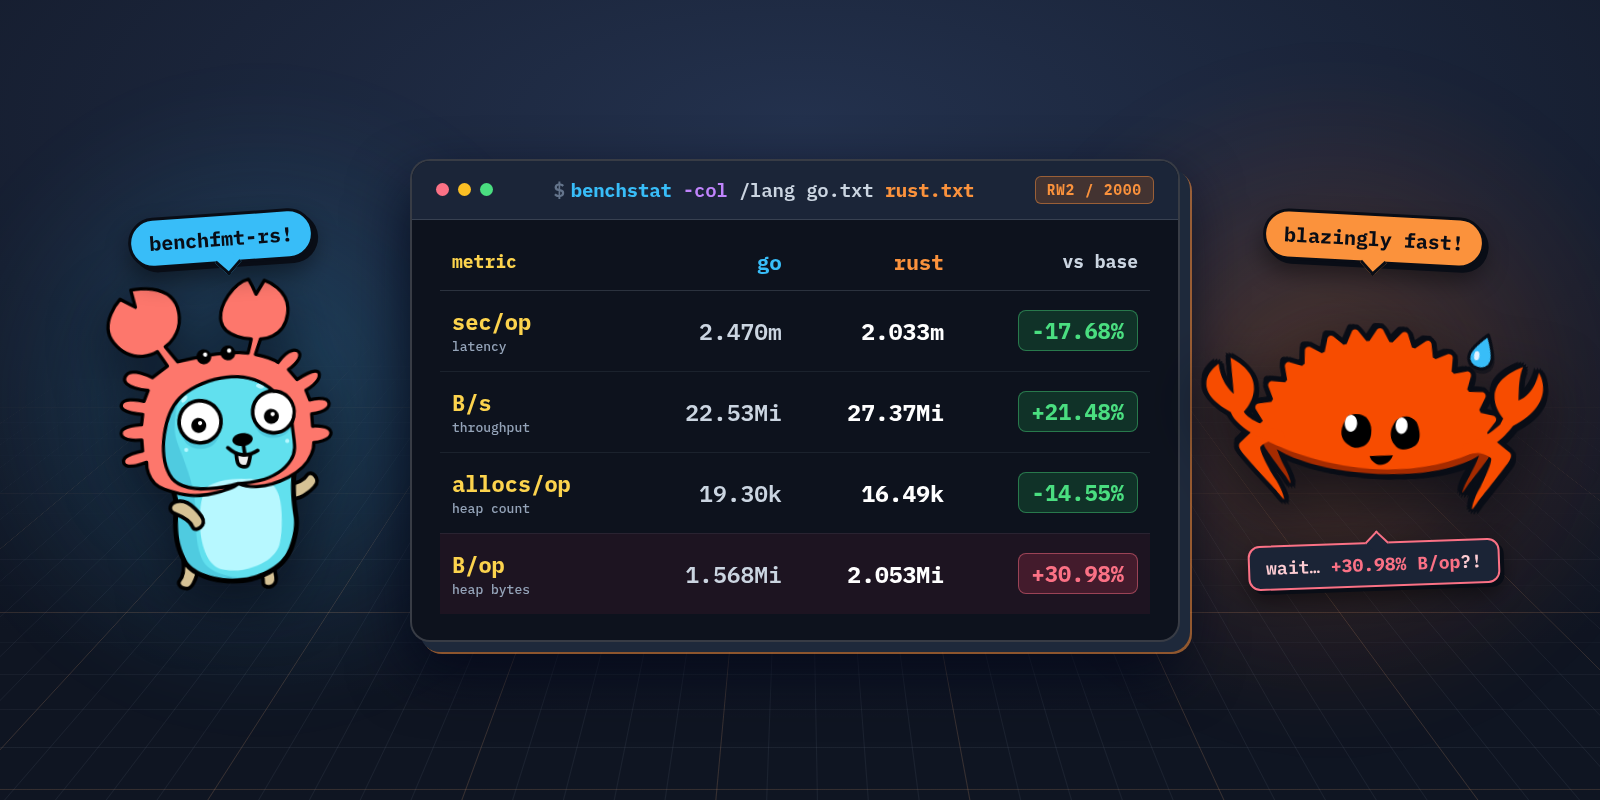
TL;DR: I built
benchfmt.rs, a zero-dependency Rust benchmark runner andCriterionconverter for Go’sbenchstat. It adds/key=valueprojections, heap tracking for allocated bytes (B/op) and objects (allocs/op) per op, andpprofprofiling.In this post, I am benchmarking
varintand Prometheus Remote Write 2.0 decoding across Go and Rust to showcase the benefits ofbenchstat-like flow in Rust. I’m also sharing some fun learnings on the way (e.g., yes Rust is faster).
Recently, I’ve been working on a few Rust projects across Google and open source. I came to Rust after years of writing performance-sensitive Go in Prometheus, Thanos, and teaching Go in the “Efficient Go” book. For me, much of Rust’s performance story is really good, until…. I wanted to run A/B microbenchmarks.
Perhaps I was spoiled by the Go benchmarking ecosystem, with the go tool -bench and benchstat in the center. To me, Rust standard benchmarking tools are lacking:
- Standard format for case comparison projections.
- Standard heap allocation measurements.
- Standard
pprofsupport. - Simple to understand reliability scoring.
DISCLAIMER: A
standardhere means something that will be familiar to large number of developers, and I biased on Go experience for sure!
As a result, I asked myself: can we get benchstat-compatible output for Rust microbenchmarks? Wouldn’t that make A/B testing easier and unlock fun Go vs Rust comparisons?
Here we are! I built benchfmt.rs, a zero-dependency Rust benchmark runner with a thread-local heap allocation counter, pprof profiler integration, and the same CLI flags as go test -bench. For those who don’t trust a new benchmarking runtime (you shouldn’t from the start!), it also ships a Criterion and libtest converter that emits Go’s benchfmt format directly.
In this blog post, we will implement the same pieces of code in Go and Rust, benchmark them across different Rust frameworks, and compare the results. We might learn something new along the way (I did when building this!). Enjoy!
All benchmark code and raw outputs live in bwplotka/benchmarks/benchmarks/rust-go-decode.
Benchmarking two workloads
Let’s pick two workloads to implement and benchmark in both Go and Rust. I am particularly curious about protobuf decoding performance, which, funny enough, is often one of the main costs of running distributed systems these days. Thus, let’s decode our Prometheus Remote Write 2.0 protocol. Because protobuf code generators have different maturity and trade-offs across languages, let’s also measure something simpler alongside it, a standalone varint decoder.
Workload details:
DecodeVarints. A 36-line unsigned LEB128 varint stream decoder. Varints are the integer encoding underneath Protocol Buffers. Our fixturevarints_2000.binis4,798bytes and packs2,000uint64values mixing 1-byte symbol indices, 2-byte bucket offsets, 4-byte deltas, and 6-byte millisecond Unix timestamps. The function writes into a preallocated2,000-element slice with zero heap allocations.DecodeRemoteWrite2. A full HTTP request body decoder for Snappy-compressed Remote Write 2.0 (io.prometheus.write.v2.Request) payloads. We test batches of200and2,000series, where2,000matches Prometheus’s defaultmax_samples_per_send. The2,000-series fixture mixes counters, gauges, classic and native histograms,1,000trace exemplars, and metric metadata. Remote Write 2.0 interns all strings into a top-levelsymbolstable and stores packed varintlabels_refsper series. That shrinks the2,000-series batch to244.9 KiBuncompressed and57.0 KiBSnappy-compressed.
Implementing and benchmarking in Go
Let’s start with Go. First, DecodeVarints writes straight into a caller-provided slice, with a fast path for single-byte values below 0x80:
func DecodeVarints(src []byte, dst []uint64) (int, error) {
	n := 0
	i := 0
	for i < len(src) {
		if n >= len(dst) {
			return n, ErrDstTooSmall
		}
		b := src[i]
		i++
		if b < 0x80 {
			dst[n] = uint64(b)
			n++
			continue
		}
		x := uint64(b & 0x7f)
		shift := uint(7)
		for {
			if i >= len(src) {
				return n, ErrUnexpectedEOF
			}
			b = src[i]
			i++
			x |= uint64(b&0x7f) << shift
			if b < 0x80 {
				break
			}
			shift += 7
			if shift >= 64 {
				return n, ErrOverflow
			}
		}
		dst[n] = x
		n++
	}
	return n, nil
}
Second, for DecodeRemoteWrite2, we tune the Go implementation the way Prometheus runs in production rather than benchmarking slow reflection-based unmarshaling. We pair github.com/golang/snappy, which uses x86-64 assembly on linux/amd64, with vtprotobuf and its generated, optimized UnmarshalVT decoder:
func DecodeRemoteWrite2(compressed []byte) (*writev2.Request, error) {
	raw, err := snappy.Decode(nil, compressed)
	if err != nil {
		return nil, err
	}
	req := &writev2.Request{}
	if err := req.UnmarshalVT(raw); err != nil {
		return nil, err
	}
	return req, nil
}
Now let’s measure the efficiency of our Go code!
Notice Go’s /key=value sub-benchmark names (samples=2000/lang=go), which let Go’s official benchstat tool pivot across /lang or /samples later, along with b.SetBytes, b.ReportAllocs, and for b.Loop():
func BenchmarkDecodeVarints(b *testing.B) {
	manifest := ensureFixtures(b)
	raw, err := os.ReadFile(filepath.Join("testdata", "varints_2000.bin"))
	if err != nil {
		b.Fatalf("read varints: %v", err)
	}
	dst := make([]uint64, manifest.VarintsCount)

	// Encode dimensions as /key=value so benchstat can pivot across /samples or /lang.
	b.Run("samples=2000/lang=go", func(b *testing.B) {
		b.SetBytes(int64(len(raw)))
		b.ReportAllocs()
		// NOTE: b.Loop() resets the timer on its first call, stops it on exit, and keeps
		// call arguments and results alive without package-level sink variables.
		for b.Loop() {
			n, err := DecodeVarints(raw, dst)
			if err != nil || n != manifest.VarintsCount {
				b.Fatalf("unexpected decode result: n=%d err=%v", n, err)
			}
		}
	})
}

func BenchmarkDecodeRemoteWrite2(b *testing.B) {
	ensureFixtures(b)

	for _, samples := range []int{200, 2000} {
		file := fmt.Sprintf("rw2_%d.snappy", samples)
		compressed, err := os.ReadFile(filepath.Join("testdata", file))
		if err != nil {
			b.Fatalf("read %s: %v", file, err)
		}

		b.Run(fmt.Sprintf("samples=%d/lang=go", samples), func(b *testing.B) {
			b.SetBytes(int64(len(compressed)))
			b.ReportAllocs()
			for b.Loop() {
				req, err := DecodeRemoteWrite2(compressed)
				if err != nil || len(req.Timeseries) != samples {
					b.Fatalf("unexpected v2 decode: err=%v", err)
				}
			}
		})
	}
}
Finally, let’s run 6 benchmark runs (“epochs”) for 2s each at -cpu 2 on a 24-core Intel Xeon 2.20GHz Linux workstation (Go 1.26.8, Rust 1.99.1):
go test -run '^$' -bench '^BenchmarkDecode' \
    -benchtime 2s -count 6 -cpu 2 -timeout 999m -benchmem \
| tee results/go.txt
One epoch looks as follows:
goos: linux
goarch: amd64
pkg: github.com/bwplotka/benchmarks/benchmarks/rust-go-decode
cpu: Intel(R) Xeon(R) CPU @ 2.20GHz
BenchmarkDecodeVarints/samples=2000/lang=go-2          279861      8514 ns/op   563.52 MB/s        0 B/op        0 allocs/op
BenchmarkDecodeRemoteWrite2/samples=200/lang=go-2        8467    264321 ns/op    31.43 MB/s   195296 B/op     2189 allocs/op
BenchmarkDecodeRemoteWrite2/samples=2000/lang=go-2        976   2448633 ns/op    23.84 MB/s  1643970 B/op    19297 allocs/op
Implementing and benchmarking in Rust with Criterion
Now let’s port both decoders and benchmarks to Rust. First, decode_varints mirrors the Go loop line for line:
pub fn decode_varints(src: &[u8], dst: &mut [u64]) -> Result<usize, VarintError> {
    let mut n = 0usize;
    let mut i = 0usize;
    while i < src.len() {
        if n >= dst.len() {
            return Err(VarintError::DstTooSmall);
        }
        let mut b = src[i];
        i += 1;
        if b < 0x80 {
            dst[n] = u64::from(b);
            n += 1;
            continue;
        }
        let mut x = u64::from(b & 0x7f);
        let mut shift = 7u32;
        loop {
            if i >= src.len() {
                return Err(VarintError::UnexpectedEof);
            }
            b = src[i];
            i += 1;
            x |= u64::from(b & 0x7f) << shift;
            if b < 0x80 {
                break;
            }
            shift += 7;
            if shift >= 64 {
                return Err(VarintError::Overflow);
            }
        }
        dst[n] = x;
        n += 1;
    }
    Ok(n)
}
Second, decode_remote_write2 pairs the snap crate with prost compile-time generated Message structs:
pub fn decode_remote_write2(compressed: &[u8]) -> Result<proto::v2::Request, String> {
    let raw = snap::raw::Decoder::new()
        .decompress_vec(compressed)
        .map_err(|e| e.to_string())?;
    proto::v2::Request::decode(raw.as_slice()).map_err(|e| e.to_string())
}
Now, let’s write both Rust benchmarks using Criterion, the default choice for stable-Rust microbenchmarking. We keep the same /key=value benchmark IDs and configure Throughput::BytesDecimal to match Go’s decimal MB/s:
fn bench_varints(c: &mut Criterion) {
    // Resolve testdata/ from the crate directory baked in at compile time.
    let root = Path::new(env!("CARGO_MANIFEST_DIR")).join("testdata");
    let raw = fs::read(root.join("varints_2000.bin")).unwrap();
    // Preallocate the output buffer outside the timed loop so each op does 0 heap allocs.
    let mut dst = vec![0u64; 2000];

    // Group + function ID join into "DecodeVarints/samples=2000/lang=rust" to match Go's b.Run.
    let mut group = c.benchmark_group("DecodeVarints");
    // Report decimal MB/s (1e6 B/s) to match Go's b.SetBytes; Throughput::Bytes prints MiB/s.
    group.throughput(Throughput::BytesDecimal(raw.len() as u64));
    group.bench_function("samples=2000/lang=rust", |b| {
        // b.iter runs the closure across Criterion's warmup and 100 linear-ramp samples.
        b.iter(|| {
            // std::hint::black_box is an LLVM optimization barrier: Unlike Go's b.Loop(), Rust
            // would constant-fold known inputs or delete unused work without black_box hints.
            let n = decode_varints(black_box(&raw), black_box(&mut dst)).unwrap();
            assert_eq!(n, 2000);
            // Observe the written buffer so LLVM cannot optimize away stores into dst.
            black_box(dst[n - 1]);
        });
    });
    group.finish();
}

fn bench_remote_write2(c: &mut Criterion) {
    let root = Path::new(env!("CARGO_MANIFEST_DIR")).join("testdata");
    let mut group = c.benchmark_group("DecodeRemoteWrite2");

    for samples in [200usize, 2000usize] {
        let file = format!("rw2_{samples}.snappy");
        let compressed = fs::read(root.join(file)).unwrap();

        group.throughput(Throughput::BytesDecimal(compressed.len() as u64));
        let id = format!("samples={samples}/lang=rust");
        group.bench_function(&id, |b| {
            b.iter(|| {
                let req = decode_remote_write2(black_box(&compressed)).unwrap();
                assert_eq!(req.timeseries.len(), samples);
                // Force req to materialize before dropping at the end of the iteration.
                black_box(req);
            });
        });
    }
    group.finish();
}

// Generate the benchmark group runner and custom main() required by harness = false in Cargo.toml.
criterion_group!(benches, bench_varints, bench_remote_write2);
criterion_main!(benches);
Finally, let’s run the Criterion benchmark suite:
cargo bench --bench criterion_decode
DecodeVarints/samples=2000/lang=rust
                        time:   [5.2789 µs 5.3369 µs 5.4014 µs]
                        thrpt:  [888.29 MB/s 899.02 MB/s 908.90 MB/s]

DecodeRemoteWrite2/samples=200/lang=rust
                        time:   [237.09 µs 238.48 µs 239.95 µs]
                        thrpt:  [34.620 MB/s 34.833 MB/s 35.037 MB/s]

DecodeRemoteWrite2/samples=2000/lang=rust
                        time:   [2.0712 ms 2.0831 ms 2.0968 ms]
                        thrpt:  [27.835 MB/s 28.018 MB/s 28.179 MB/s]
Criterion downsides
Criterion is convenient when you want confidence intervals and HTML plots from a single cargo bench command without external tools. However, compared to go test and benchstat, four design choices get in the way:
-
Compile weight. Pulling in
criterionwithdefault-features = falsestill compilesclap,regex-automata,ciborium,oorandom,itertools,tinytemplate, andanes. That adds 42 transitive crates and ~19s to a coldcargo benchbuild. -
Linear-ramp sampling vs steady-state epochs.
- Go’s
testing.Bcalibrates a fixed iteration countNfor-benchtime 2sand runs-count 6equal steady-state epochs, whichbenchstatsummarizes using the outlier-resistant median and Mann-Whitney U test. - Criterion defaults to
Linearsampling: after a 3-second warmup, it collects 100 batches of[1d, 2d, ..., 100d]iterations and fits a least-squares liney = m * xthrough the origin. Because the line is forced through zero, it does not subtract a fixed timer-overhead intercept. Instead, it computes ak^2-weighted average where batch 100 carries10,000xthe weight of batch 1 and late OS spikes pull the slope up.
Comparing those two models directly introduces two measurable distortions:
- First, grouping Criterion’s 100 ramp samples into 6
benchstatepochs gives epoch 111.5xfewer iterations than epoch 6 (24,888vs286,212onDecodeVarints). Mixing short bursts with long runs inflates variance to± 5%, compared to± 1-2%in steady-state epochs. - Second, timing 100 separate closure batches adds
+8.6%overhead on microsecond loops (5.36 µsvs4.90 µs,p=0.002) and skews early allocating samples with cold allocator caches (+2.3%onDecodeRemoteWrite2).
- Go’s
-
No heap allocation tracking. Criterion reports wall-clock time and throughput only. On
DecodeVarintsat0 allocs/op, that is fine. OnDecodeRemoteWrite2, we cannot tell whetherprostmade 500 heap allocations or 500,000, or whether a refactor doubled heap churn. -
Pairwise baseline folders vs multi-dimensional tables. Criterion compares
target/criterion/<id>/baseagainstnew. You cannot feed a single run file into a table that pivots-col /samplesor-col /langacross Go and Rust.
Converting Criterion output with the benchfmt CLI
If a Rust codebase already uses Criterion, rewriting benchmarks just to get a benchstat table is not ideal. That is why benchfmt.rs includes a standalone benchfmt CLI binary. It reads benchmark.json and sample.json directly from target/criterion, extracts Throughput::BytesDecimal (or Throughput::Bytes) as decimal MB/s, and groups Criterion’s 100 samples into 6 contiguous epochs via --epochs 6:
cargo install --git https://github.com/bwplotka/benchfmt.rs

benchfmt criterion target/criterion \
    --pkg github.com/bwplotka/benchmarks/benchmarks/rust-go-decode \
    --cpu 2 \
> results/rust_criterion.txt

benchstat -col /lang results/go.txt results/rust_criterion.txt
Without touching the benchmark implementation, benchstat gives us a side-by-side Go vs Rust table:
goos: linux
goarch: amd64
pkg: github.com/bwplotka/benchmarks/benchmarks/rust-go-decode
cpu: Intel(R) Xeon(R) CPU @ 2.20GHz
                                  │     go      │                rust                │
                                  │   sec/op    │   sec/op     vs base               │
DecodeVarints/samples=2000-2        8.536µ ± 1%   5.364µ ± 5%  -37.16% (p=0.002 n=6)
DecodeRemoteWrite2/samples=200-2    271.4µ ± 3%   235.1µ ± 4%  -13.37% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   2.470m ± 5%   2.082m ± 1%  -15.72% (p=0.002 n=6)
geomean                             178.9µ        138.0µ       -22.87%

                                  │      go      │                rust                 │
                                  │     B/s      │     B/s       vs base               │
DecodeVarints/samples=2000-2        536.1Mi ± 1%   853.2Mi ± 5%  +59.15% (p=0.002 n=6)
DecodeRemoteWrite2/samples=200-2    29.19Mi ± 3%   33.70Mi ± 4%  +15.44% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   22.53Mi ± 5%   26.74Mi ± 1%  +18.67% (p=0.002 n=6)
geomean                             70.65Mi        91.60Mi       +29.67%

                                  │       go       │
                                  │      B/op      │
DecodeVarints/samples=2000-2          0.000 ± 0%
DecodeRemoteWrite2/samples=200-2    190.7Ki ± 0%
DecodeRemoteWrite2/samples=2000-2   1.568Mi ± 0%
geomean                                          ¹
¹ summaries must be >0 to compute geomean

                                  │      go       │
                                  │   allocs/op   │
DecodeVarints/samples=2000-2         0.000 ± 0%
DecodeRemoteWrite2/samples=200-2    2.189k ± 0%
DecodeRemoteWrite2/samples=2000-2   19.30k ± 0%
geomean                                         ¹
¹ summaries must be >0 to compute geomean
Now, with this view we finally have a readable, standard benchstat output Go developers love. It clearly shows the Go vs Rust efficiency for our example functions. Rust is 37.16% faster on DecodeVarints (5.36 µs vs 8.54 µs) and 13.37% to 15.72% faster on DecodeRemoteWrite2.
Unfortunately, there are some gaps:
- The
B/opandallocs/optables only have agocolumn because Criterion never recorded allocations - Criterion’s linear-ramp epochs still leave
± 5%variance onDecodeVarints.
Native benchfmt runs with benchfmt::Suite and CountingAlloc
For new Rust benchmarks, we can skip Criterion and use benchfmt::Suite with harness = false in Cargo.toml. Registering CountingAlloc as #[global_allocator] tracks every alloc, alloc_zeroed, and realloc in a thread_local! Cell<(u64, u64)> with zero atomic contention and zero external dependencies:
// Wrap Rust's System allocator globally so every heap alloc/realloc on the benchmark thread
// increments thread-local (allocs, bytes) counters for B/op and allocs/op.
#[global_allocator]
static ALLOC: CountingAlloc = CountingAlloc::new();

fn main() {
    let root = Path::new(env!("CARGO_MANIFEST_DIR")).join("testdata");
    let raw_varints = fs::read(root.join("varints_2000.bin")).unwrap();
    let rw2_200 = fs::read(root.join("rw2_200.snappy")).unwrap();
    let rw2_2000 = fs::read(root.join("rw2_2000.snappy")).unwrap();
    let mut dst = vec![0u64; 2000];

    // Parse go-test-compatible CLI flags (-bench, -benchtime, -count, -cpu, -benchmem,
    // -cpuprofile, -memprofile) from std::env::args() and set the default "pkg:" header.
    // Using the same pkg path as Go's go.mod lets `benchstat -col /lang` join Go and Rust rows.
    Suite::from_env("github.com/bwplotka/benchmarks/benchmarks/rust-go-decode")
        // Attach ALLOC so each benchmark snapshots thread-local allocation deltas per epoch.
        .with_alloc(&ALLOC)
        // Suite prepends "Benchmark" in benchfmt output, matching Go's BenchmarkDecodeVarints.
        .bench("DecodeVarints/samples=2000/lang=rust", |b| {
            b.set_bytes(raw_varints.len() as u64);
            b.report_allocs();
            // Go b.Loop() equivalent: starts timing, alloc snapshots, and any pprof capture on the
            // first call, runs the calibrated N steady-state iterations, then stops all three.
            while b.keep_running() {
                let n = decode_varints(black_box(&raw_varints), black_box(&mut dst)).unwrap();
                assert_eq!(n, 2000);
                black_box(dst[n - 1]);
            }
        })
        .bench("DecodeRemoteWrite2/samples=200/lang=rust", |b| {
            b.set_bytes(rw2_200.len() as u64);
            b.report_allocs();
            while b.keep_running() {
                let req = decode_remote_write2(black_box(&rw2_200)).unwrap();
                assert_eq!(req.timeseries.len(), 200);
                black_box(req);
            }
        })
        .bench("DecodeRemoteWrite2/samples=2000/lang=rust", |b| {
            b.set_bytes(rw2_2000.len() as u64);
            b.report_allocs();
            while b.keep_running() {
                let req = decode_remote_write2(black_box(&rw2_2000)).unwrap();
                assert_eq!(req.timeseries.len(), 2000);
                black_box(req);
            }
        })
        .run();
}
Does
CountingAllocwork with Tokio and custom allocators? Mostly yes. You can wrap custom allocators likejemallocormimallocviaCountingAlloc::with_allocator(Jemalloc). BecauseCountingAllocuses thread-local counters on the benchmark thread, single-threaded Tokiocurrent_threadworks out of the box, while multi-threaded pools liketokio::spawnorrayonneed a process-wide atomicAllocTrackerpassed toSuite::with_alloc.
Suite::from_env reads std::env::args(), auto-detects goos, goarch, and cpu, and writes the passed string as the pkg: metadata line (matching Go’s module path so benchstat joins Go and Rust rows into one table). Passing flags after -- mirrors go test:
cargo bench --bench suite_decode -- \
    -bench '^BenchmarkDecode' -benchtime 2s -count 6 -cpu 2 -benchmem \
| tee results/rust_suite.txt
First, let’s verify that benchfmt::Suite agrees with Criterion on timing, even with CountingAlloc active on every allocation:
benchstat criterion=results/rust_criterion.txt suite=results/rust_suite.txt
                                            │  criterion  │               suite               │
                                            │   sec/op    │   sec/op     vs base              │
DecodeRemoteWrite2/samples=2000/lang=rust-2   2.082m ± 1%   2.033m ± 2%  -2.33% (p=0.015 n=6)
DecodeRemoteWrite2/samples=200/lang=rust-2    235.1µ ± 4%   231.5µ ± 1%  -1.55% (p=0.004 n=6)
DecodeVarints/samples=2000/lang=rust-2        5.364µ ± 5%   4.902µ ± 2%  -8.60% (p=0.002 n=6)
geomean                                       138.0µ        132.1µ       -4.21%
On DecodeRemoteWrite2, Criterion and benchfmt::Suite agree within 1.6% to 2.3%, while Suite’s steady-state 2s epochs tighten worst-case variance from ± 4-5% down to ± 1-2%. On DecodeVarints, while b.keep_running() runs 490,000 back-to-back iterations in one tight loop instead of 100 short ramp batches, clocking 4.90 µs vs 5.36 µs.
Comparing Go vs Rust
Now let’s run the full Go vs Rust comparison with results/rust_suite.txt:
benchstat -col /lang results/go.txt results/rust_suite.txt
goos: linux
goarch: amd64
pkg: github.com/bwplotka/benchmarks/benchmarks/rust-go-decode
cpu: Intel(R) Xeon(R) CPU @ 2.20GHz
                                  │     go      │                rust                │
                                  │   sec/op    │   sec/op     vs base               │
DecodeVarints/samples=2000-2        8.536µ ± 1%   4.902µ ± 2%  -42.56% (p=0.002 n=6)
DecodeRemoteWrite2/samples=200-2    271.4µ ± 3%   231.5µ ± 1%  -14.71% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   2.470m ± 5%   2.033m ± 2%  -17.68% (p=0.002 n=6)
geomean                             178.9µ        132.1µ       -26.12%

                                  │      go      │                rust                 │
                                  │     B/s      │     B/s       vs base               │
DecodeVarints/samples=2000-2        536.1Mi ± 1%   933.3Mi ± 2%  +74.09% (p=0.002 n=6)
DecodeRemoteWrite2/samples=200-2    29.19Mi ± 3%   34.22Mi ± 1%  +17.23% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   22.53Mi ± 5%   27.37Mi ± 2%  +21.48% (p=0.002 n=6)
geomean                             70.65Mi        95.62Mi       +35.35%

                                  │       go       │                 rust                  │
                                  │      B/op      │     B/op      vs base                 │
DecodeVarints/samples=2000-2          0.000 ± 0%       0.000 ± 0%        ~ (p=1.000 n=6) ¹
DecodeRemoteWrite2/samples=200-2    190.7Ki ± 0%     271.9Ki ± 0%  +42.59% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   1.568Mi ± 0%     2.053Mi ± 0%  +30.98% (p=0.002 n=6)
geomean                                          ²                 +23.15%               ²
¹ all samples are equal
² summaries must be >0 to compute geomean

                                  │      go       │                 rust                 │
                                  │   allocs/op   │  allocs/op   vs base                 │
DecodeVarints/samples=2000-2         0.000 ± 0%      0.000 ± 0%        ~ (p=1.000 n=6) ¹
DecodeRemoteWrite2/samples=200-2    2.189k ± 0%     1.905k ± 0%  -12.97% (p=0.002 n=6)
DecodeRemoteWrite2/samples=2000-2   19.30k ± 0%     16.49k ± 0%  -14.55% (p=0.002 n=6)
geomean                                         ²                 -9.40%               ²
¹ all samples are equal
² summaries must be >0 to compute geomean
Look closely at the B/op and allocs/op tables. That is the kind of surprise you miss without allocation counters:
- Rust makes 14.55% fewer heap allocations at
2,000series (16,490vs Go’s19,297 allocs/op). Go’sprotoc-gen-gogenerates pointer slices such as[]*TimeSeriesand[]*Sample, allocating every nested struct separately on the heap. Rust’sproststoresVec<TimeSeries>andVec<Sample>inline by value. - Yet Rust requests 30.98% more heap bytes at
2,000series (2.05 MiBvs Go’s1.57 MiB) and 42.59% more at200series (271.9 KiBvs190.7 KiB)!
Bonus: go tool pprof profiling to tell WHERE certain overhead exists benchmarks in Go and Rust
benchstat tells us what changed, while pprof tells us why. With features = ["pprof"] and [profile.bench] debug = 1 in Cargo.toml, benchfmt::Suite supports the same -cpuprofile, -memprofile, and -memprofilerate flags as go test. Every .pb.gz file opens directly in go tool pprof -http=:8080 or pprof.me.
CPU profiling DecodeVarints
DecodeVarints does zero heap allocations in both languages, yet Rust finishes in 4.90 µs while Go takes 8.54 µs for the same loop. Let’s capture single-threaded CPU profiles from both runners:
go test -run '^$' -bench '^BenchmarkDecodeVarints$' -benchtime 5s -count 1 -cpu 1 \
    -cpuprofile /tmp/go_varints_cpu.pb.gz

cargo bench --bench suite_decode -- \
    -bench '^BenchmarkDecodeVarints/' -benchtime 3s -count 1 -cpu 1 \
    -cpuprofile /tmp/rust_varints_cpu.pb.gz
Opening the source view in pprof shows where each compiler spends its cycles:
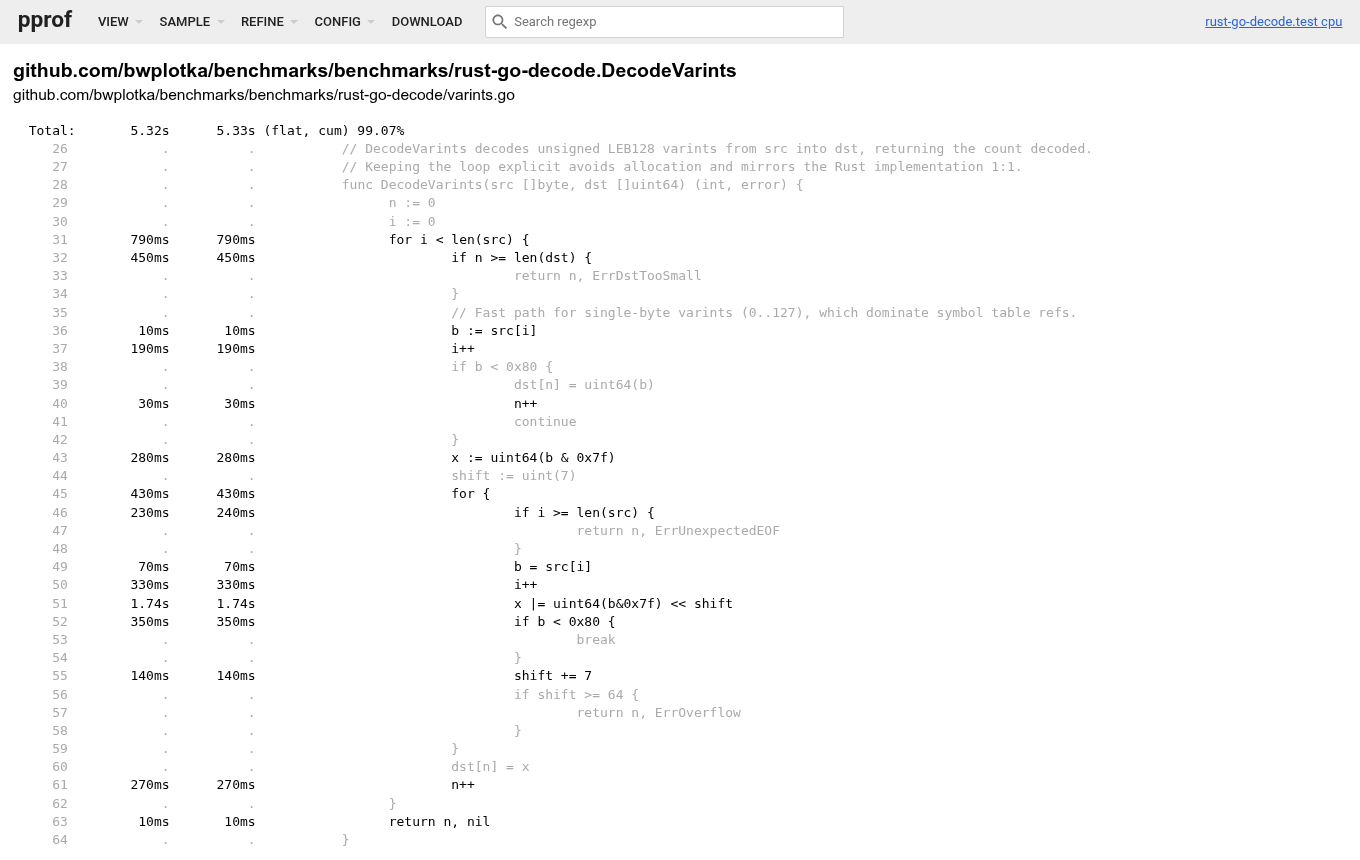
DecodeVarints CPU source profile. Explore the interactive profile on pprof.me.
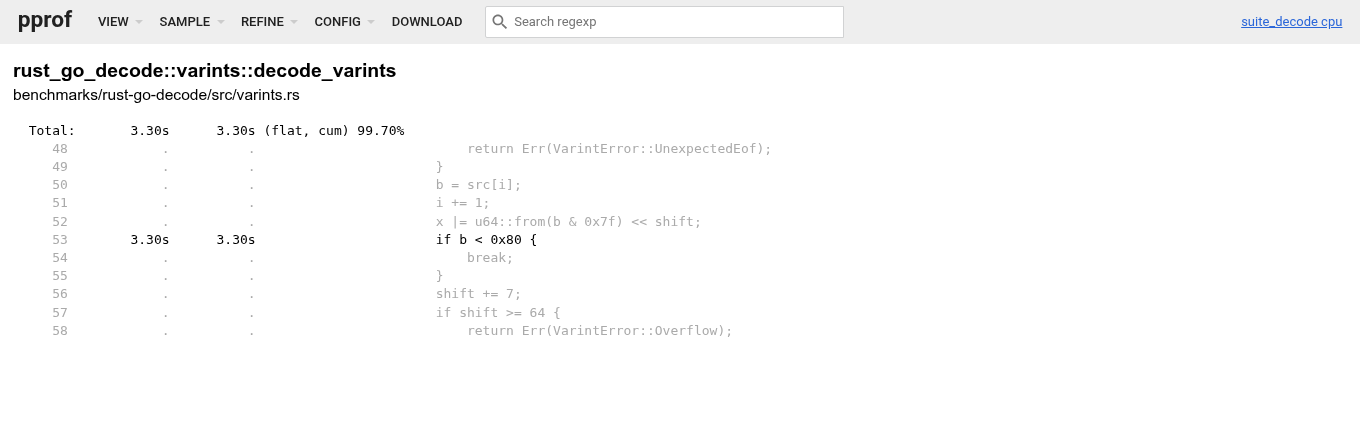
decode_varints CPU source profile. Explore the interactive profile on pprof.me.
Both languages spend over 99% of CPU inside the varint loop. Go, however, burns 1.74s (32.3%) on x |= uint64(b&0x7f) << shift alone and 1.24s (23.0%) on the outer loop checks. Inspecting go tool objdump and objdump -d shows two codegen differences behind the 42.56% gap:
- Loop unrolling and 64-bit shift masking. Because
shiftsteps by7up to64(at most 9 bytes), LLVM unrolls Rust’s inner continuation loop. Every variable<< shiftbecomes a constant shift (shl $0x7,shl $0xe,shl $0x15, …) with noshiftcounter orshift >= 64branch. Go keeps the inner loop rolled and definesx << shiftas0whenshift >= 64, whereas x86SHLQ CLmasks modulo 64. That forces Go to emitSHLQ CL,CMPQ $64,SBBQ, andANDQon every continuation byte. - Signed
intvs unsignedusizeindices. Go’siandnare signedint, soi < len(src)andn >= len(dst)do not prove non-negativity across the loop back-edge. Go emits duplicate unsignedCMPQ/JBEslice bounds checks beforesrc[i]anddst[n], while LLVM removes the inner checks on Rust’s unsignedusizeindices and inlinesdecode_varintsintowhile b.keep_running().
CPU and heap profiling DecodeRemoteWrite2
Next, let’s collect -cpuprofile and exact -memprofile captures on the 2,000-series Remote Write 2.0 benchmark:
# CPU profiles: 3s at -cpu 1.
go test -run '^$' -bench '^BenchmarkDecodeRemoteWrite2/samples=2000/' -benchtime 3s -count 1 -cpu 1 \
    -cpuprofile /tmp/go_rw2_cpu.pb.gz
cargo bench --bench suite_decode -- \
    -bench 'DecodeRemoteWrite2/samples=2000' -benchtime 3s -count 1 -cpu 1 \
    -cpuprofile /tmp/rust_rw2_cpu.pb.gz

# Exact heap profiles: 50 iterations with every allocation sampled.
go test -run '^$' -bench '^BenchmarkDecodeRemoteWrite2/samples=2000/' -benchtime 50x -count 1 -cpu 1 \
    -memprofile /tmp/go_rw2_mem.pb.gz -memprofilerate 1
cargo bench --bench suite_decode -- \
    -bench 'DecodeRemoteWrite2/samples=2000' -benchtime 50x -count 1 -cpu 1 \
    -memprofile /tmp/rust_rw2_mem.pb.gz -memprofilerate 1
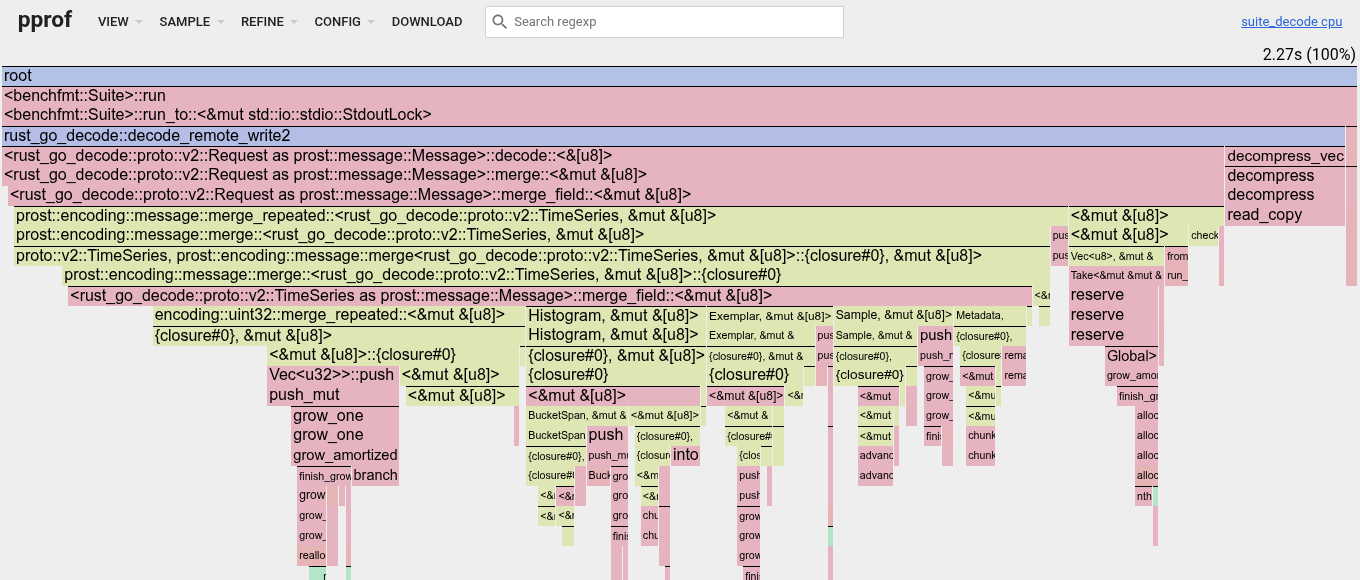
The two CPU flamegraphs show very different bottlenecks:
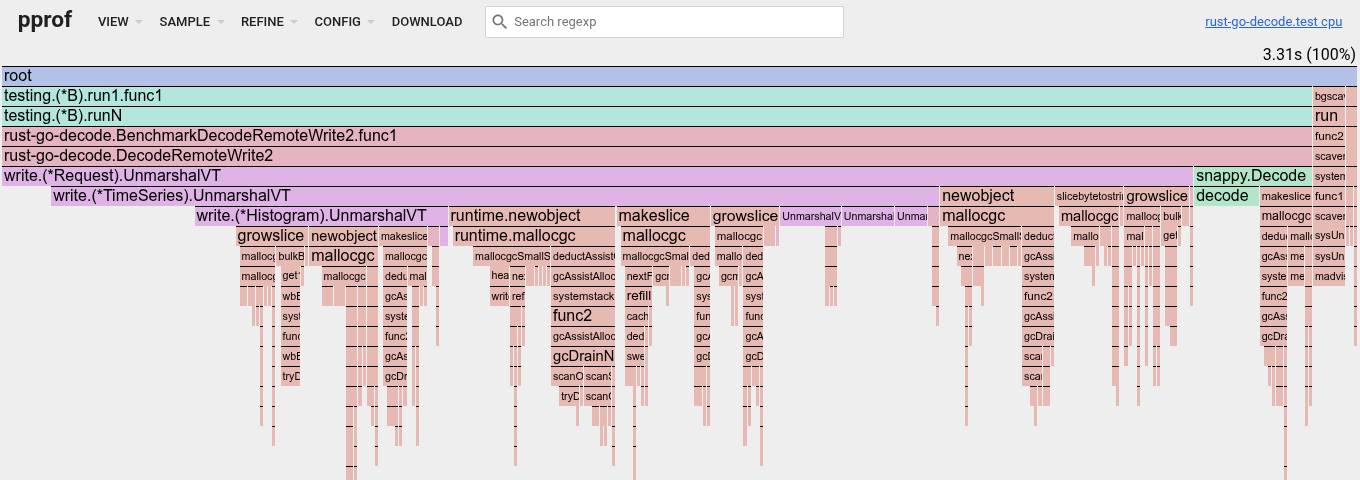
DecodeRemoteWrite2 CPU flamegraph (samples=2000). Explore the interactive profile on pprof.me.
DecodeRemoteWrite2 CPU flamegraph (samples=2000). Explore the interactive profile on pprof.me.
Go’s x86-assembly snappy.Decode at ~0.12 ms/op actually beats pure-Rust snap at ~0.18 ms/op, and vtprotobuf’s own wire parsing takes only ~0.95 ms/op. Go still loses overall because runtime.mallocgc and GC assist take 54.1% of all on-CPU time, or ~1.34 ms/op, allocating and scanning 19,297 heap objects.
In Rust, 71.1% of CPU time goes to prost field decoding, 8.9% to snap decompression, and 18.7% to RawVecInner::grow_amortized under Vec::push and Vec::reserve. The alloc_space heap profiles show why RawVecInner::grow_amortized is so busy and why Rust allocates 30.98% more B/op than Go:
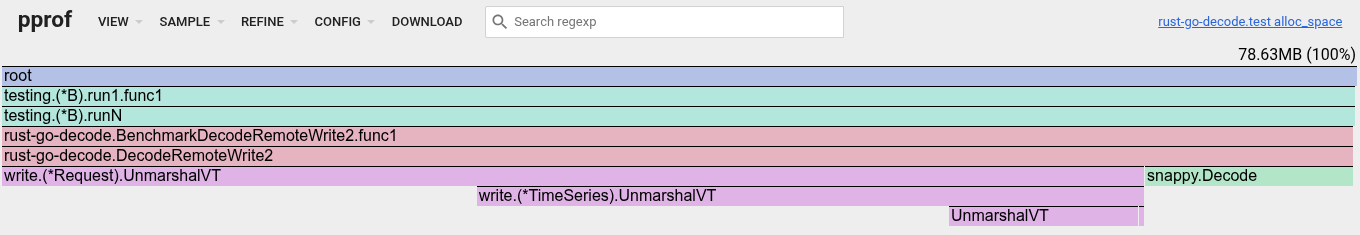
DecodeRemoteWrite2 heap alloc_space flamegraph (50x). Explore the interactive profile on pprof.me.
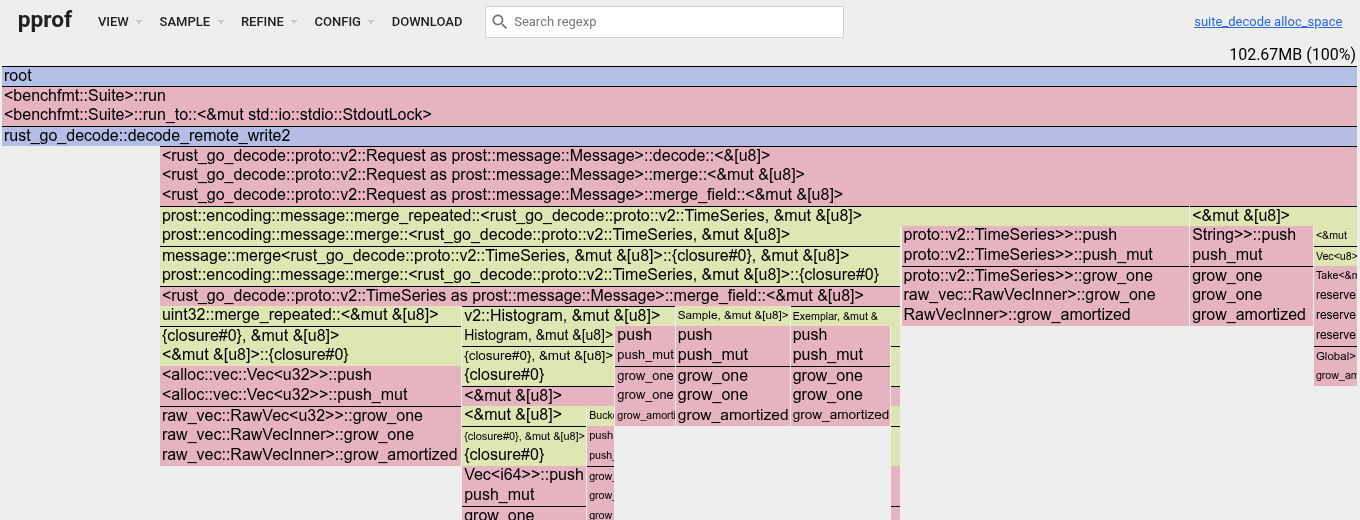
DecodeRemoteWrite2 heap alloc_space flamegraph (50x). Explore the interactive profile on pprof.me.
Go’s UnmarshalVT preallocates slices and structs close to their final size, totaling 1.57 MiB/op. Rust allocates 2.05 MiB/op, and 88.4% of those bytes come from RawVec capacity doubling inside prost:
prostdecodes packedrepeated uint32 labels_refsoneu32at a time withVec::pushinstead of pre-sizing from the wire byte length. Every series grows itsVec<u32>through capacities4 -> 8 -> 16 -> 32, accounting for23.0%of all allocated bytes.- Growing
Vec<v2::TimeSeries>from0to2,048copies inline 112-byte structs at each power of two, which is21.3%of allocated bytes. Go only grows an 8-byte[]*TimeSeriespointer slice. - Pushing one 24-byte
Sampleinto an emptyVec<Sample>jumps straight to capacity4due toRawVec::MIN_NON_ZERO_CAP, adding another8.5%of allocated bytes across1,900series.
However, even with that extra Vec churn, glibc thread-cache reallocations in Rust cost ~3.5x less CPU than Go’s mallocgc and GC assist, so -memprofile points straight to a Vec::with_capacity fix.
Checking our microbenchmarks with a standalone binary and /usr/bin/time -v
Ok, those microbenchmarks are great, but let’s verify our efficiency numbers against the real program!
Microbenchmarks run inside an artificial loop with a hot instruction cache, a warm allocator, and a custom #[global_allocator] wrapper in suite_decode. Do those ns/op and B/op numbers hold up in an unmodified release binary?
To check, I wrote two standalone CLI binaries:
Each binary runs N iterations, accumulates a checksum, and optionally keeps K decoded messages alive via --retain K to simulate an ingestion queue. I ran both under GNU /usr/bin/time -v with GOMAXPROCS=2 on Go to match -cpu 2:
cargo build --release --bin verify_decode
/usr/bin/time -v ./target/release/verify_decode --case rw2_2000 --iters 1000 --retain 0
/usr/bin/time -v ./target/release/verify_decode --case rw2_2000 --iters 1000 --retain 1000
Here is what /usr/bin/time -v reported across all runs:
| Run | Iters | Microbench | Binary wall | Total CPU | CPU % | Max RSS |
|---|---|---|---|---|---|---|
Rust varints |
500,000 |
4.90 µs |
5.74 µs |
2.89s (5.78 µs/op) |
99% |
2.44 MiB |
Go varints |
500,000 |
8.54 µs |
8.64 µs |
4.34s (8.68 µs/op) |
100% |
6.11 MiB |
Rust rw2_2000 |
1,000 |
2.03 ms |
2.22 ms |
2.22s (2.22 ms/op) |
99% |
4.21 MiB |
Go rw2_2000 |
1,000 |
2.47 ms |
2.97 ms |
4.28s (4.28 ms/op) |
144% |
15.98 MiB |
Rust rw2_2000 --retain 1000 |
1,000 |
2.03 ms |
2.75 ms |
3.18s (3.18 ms/op) |
99% |
1,292.4 MiB |
The process-level numbers show a few important details:
CountingAllocdid not distort latency. The standalone Rust binary ranrw2_2000at2.22 ms/opacross1,000cold-start iterations, close to2.03 ms/opinbenchfmt::Suitewhile counting16,490allocations per iteration.B/opmeasures allocator churn, not live memory. Over1,000iterations ofrw2_2000, Rust requested2.00 GiBfrom the allocator, yet peak RSS withretain=0stayed at4.21 MiB. Dropping eachRequestat the end of the loop letsglibcreuse the freed thread-cache chunks on the next iteration without asking Linux for new pages. Keeping all1,000batches alive with--retain 1000raised RSS to1,292.4 MiB(1.29 MiBper retained message after temporary Snappy andVec-doubling buffers were freed) and split CPU into2.12suser +1.06skernelsystime for page faults.- Wall-clock
ns/ophides Go’s background GC cost. Inbenchstat, Rust was17.68%faster than Go onrw2_2000. Under/usr/bin/time -vatGOMAXPROCS=2, Rust used99%of one core and4.21 MiBRSS, while Go hit144%CPU,4.28 msof CPU time per op, and15.98 MiBRSS. LeavingGOMAXPROCSunrestricted on all 24 cores pushed Go to220%CPU, or7.13 msof CPU time per op, and18.53 MiBRSS as background GC threads swept heap objects. Across the whole process, Rust used 1.9x to 3.2x less CPU and 3.8x to 4.4x less RAM per request.
Summary
In general I think Rust has real potential in this AI era:
- It has extreme compile-time verification, including strict ownership and memory safety checks, which is ideal when AI generates code.
- It takes ages and can be annoying to program in by hand (sorry!), but AI writes a lot of code nowadays. Code mostly has to be readable for reviews, and Rust is good enough at that.
- It has a strong columnar storage ecosystem around crates like
arrow-rs. - It has no garbage collector, gives more control over memory allocations, and is clearly faster!
In terms of benchmarking, having both benchfmt tools in Rust lets you match the workflow to the job:
- Run
benchfmt criterion target/criterionon existing Criterion suites when you wantbenchstatA/B tables across commits or languages without editing benchmark code. - Use
benchfmt::SuiteandCountingAllocwithfeatures = ["pprof"]for new Rust microbenchmarks to get faststd-only compiles, steady-state epochs,B/opandallocs/optracking, andpprofprofiles.
Give benchfmt.rs a spin and let me know on GitHub what breaks or what is missing!
Comments